Jev
for SEO
SEO at scale is thousands of tiny judgments. Jev answers each one with a yes, a no, or a probability, in a few hundred milliseconds, for a fraction of a cent. These are the four jobs that turns into, with every request written out.
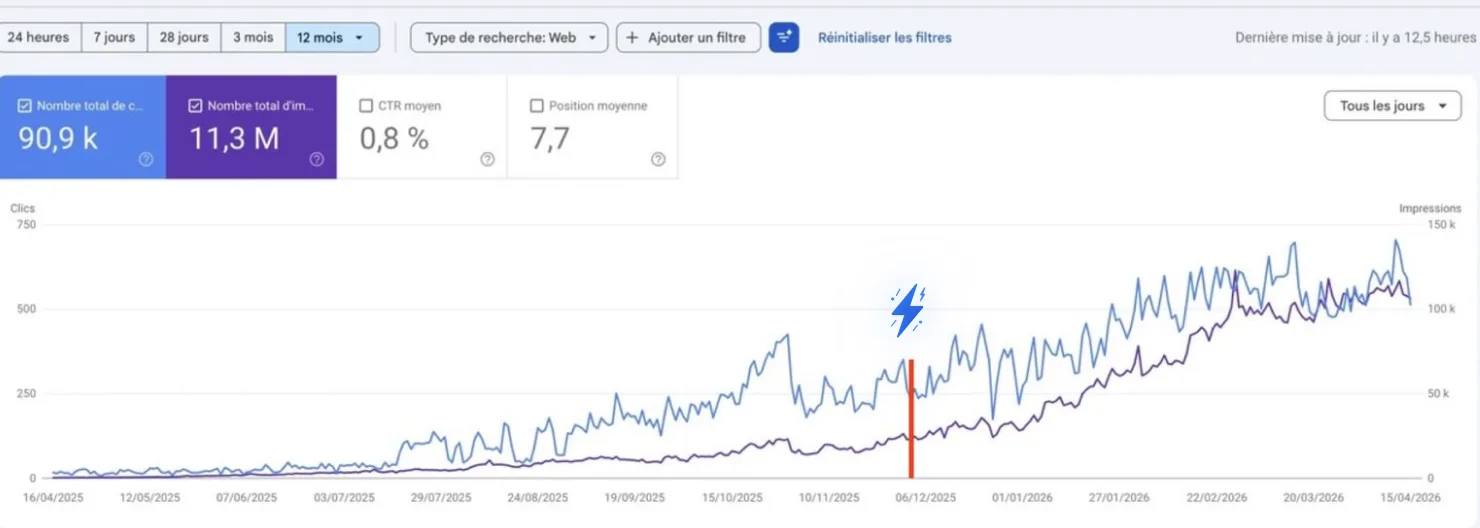
How one founder went from 250 to 750 clicks a day on judgments like these →
Free · No credit card required
Hey there, I'm Nicholas 👋
I grew my last B2C app to 15K Google clicks/month as a solo founder, then sold it. Turns out I fell in love with SEO along the way.
So now I'm building ChatSEO.app — an all-in-one SEO employee whose job is to make sure you rank #1 in Google and in AI search.
This page is what I'd hand that employee the day Jev lands in its toolbox. Try it free →
Full disclosure before anything else. I don't have access to Jev yet. It launched on 15 September 2026 behind a waitlist, and I'm on it like everyone else.
Everything on this page is built from TypeSafe's documentation and cookbooks, the launch post, the open-source projects that appeared in the first week, roughly five hundred Hacker News comments, and what I know about doing SEO at scale. Every workflow below is a hypothesis: the request is written out in full so you can run it the day you get in, and so can I. When I do, I'll update this page with what held up and what didn't.
An LLM talks. Jev decides.
The whole idea fits in one sentence: Jev doesn't generate text. You send it some state and a typed question, and it returns a probability.
Jev is the first model from TypeSafe, a San Francisco lab founded by Diogo Almeida, who worked at OpenAI on the instruction-following methods behind ChatGPT. They call it a "System One" model, after Kahneman's fast, intuitive mode of thinking. It has no chat interface and no chain of thought. It reads your input and puts probability mass on the answers you allowed. That's the whole trick, and it has three consequences that matter for SEO.
- It cannot answer outside the schema. Ask "commercial, informational, transactional or navigational?" and you get one of those four with a probability each. There is no fifth answer, no preamble, no "great question!", no JSON that fails to parse on row 4,812.
- It is fast because it doesn't write. TypeSafe quotes 70 to 500 milliseconds end to end. Third parties measured a median of about 244ms through Vercel's gateway. Questions in one request run in parallel, so asking forty costs about the same latency as asking one.
- It is priced like a database query. Published pricing is $0.042 per million input tokens and nothing for output. On that price, judging a 50,000-keyword export is a back-of-envelope dime. Sampling 500 and guessing the rest stops being a rational trade-off.
The three question types
Every request is one state plus a map of named questions. There are exactly three kinds, and every SEO judgment on this page is one of them.
| Type | Asks | Returns | SEO use |
|---|---|---|---|
| noul | Is this statement true? | noul: probability of yes, 0 to 1 | Keep or prune. Same intent or not. Claim supported or not. |
| choice | Which one of these options? | choice + a probability per option + confidence | Intent class. Funnel stage. Which page should win. |
| score | Where on this rubric? | score (weighted position) + probabilities + confidence | Draft quality. Brief coverage. Severity of a cannibalisation. |
The names are theirs, not mine. "Noul" is what TypeSafe calls a yes/no question. Two response fields do the real work downstream: the probability tells you the answer, and the confidence tells you whether to act on it without a human. TypeSafe's own guidance is act automatically above 0.9, act cautiously between 0.5 and 0.9, and route to a person below 0.5. Every workflow below uses those three bands.
That diagram is the whole architecture, and it's the opposite of how most people use an LLM for SEO. You don't ask Jev to "analyse my keywords". You keep the loop in a script, hand Jev one narrow question per row, and let thresholds in your own code decide what happens next. TypeSafe's phrase for it is "keep code in control and give System One narrow, structured decisions". Every SEO tool built on chat prompts got this backwards.
What Jev is bad at, from TypeSafe's own list
The docs ship a page called "jaggedness" for the current model, jev-1.13, and it changes how you write questions. The ones that bite SEO work:
- It answers the question you wrote, not the one you meant. Negations and edge cases are read literally. "Is this query NOT relevant" will burn you. Phrase every noul so that a high value means yes to something positive.
- It cannot count. Word counts, occurrences, number of H2s: it recognises the shape of an answer rather than tallying. Code counts. Jev judges.
- It reads dates and numbers as text. "Did position improve" is a spreadsheet question. Don't ask it.
- Irrelevant state is a distractor. Accuracy falls as the state fills with things unrelated to the decision. This is why the batch sizes below are conservative and why each question names the exact row it's about.
- It is not immune to being wrong. "Cannot hallucinate" means it cannot answer outside your schema. It can still pick the wrong option inside it. The confidence field is what tells you when.
The guide is four parts: get access (three routes, one of which works today), the four workflows from the post in the post's order, the routine that keeps them from becoming four jobs, and the mistakes I expect to make first.
Get access: three routes, and one you can use today
The direct API is waitlisted. The wire format is already public and already cloned, which means you can build the workflows now and swap the base URL later.
Route 1 — TypeSafe direct
The real thing. Waitlist at the time of writing.
Sign up at console.typesafe.ai. When you're in you get a TYPESAFE_API_KEY, a Python SDK (pip install typesafe-sdk), a JavaScript SDK, and one endpoint. Every request on this page is written against it.
POST https://api.typesafe.ai/v1/systemone
Authorization: Bearer $TYPESAFE_API_KEY
Content-Type: application/json
Route 2 — Through Vercel's AI Gateway
The route the first third-party libraries call "the easiest way to get Jev right now".
Vercel's AI Gateway lists Jev as a model, billed through your Vercel account with an AI_GATEWAY_API_KEY. Open-source eval libraries like jevals already use it as their default backend and report the same request shape and the same sub-second latency. If you have a Vercel account, this is the first thing to try.
Route 3 — An open-weight clone on your Mac, today
Not Jev. Not as smart. Same request and response shape, so the workflows port unchanged.
Within a week of launch the community shipped models that speak the System One format: Kev (Qwen3-based, runs on a 32GB Mac), Laya (ModernBERT, around 10ms on Apple Silicon), open-jev (Gemma 3 4B) and a server called verdict that turns any llama.cpp model into a /v1/systemone endpoint. None of them are TypeSafe's, and their accuracy on real SEO judgments is unmeasured. What they give you is a way to write, test and debug every workflow below against your own data now, then point it at the real model when your key arrives.
The test that matters. Whatever backend you use, hand-label 50 rows first. Run the workflow. Count the disagreements. If it's under 5, trust the ≥ 0.9 band. If it's over 10, rewrite the question, not the threshold. That 50-row check is the difference between using Jev and trusting a number you never verified.
The loop every workflow runs in
Thirty lines of Python. Replace the question builder per workflow; nothing else changes.
import os, csv, json, time, requests

URL = "https://api.typesafe.ai/v1/systemone"
HEADERS = {"Authorization": f"Bearer {os.environ['TYPESAFE_API_KEY']}"}
BATCH = 200          # rows per request. Start here; drop to 100 if agreement on your 50-row sample falls.

def ask(state, questions):
    for attempt in range(5):
        r = requests.post(URL, headers=HEADERS,
                          json={"model": "jev-latest", "state": state, "questions": questions})
        if r.status_code in (429, 529):          # rate-limited or overloaded: back off, never hammer
            time.sleep(2 ** attempt); continue
        r.raise_for_status()
        return r.json()["answers"]
    raise RuntimeError("gave up after 5 attempts")

def run(rows, build_state, build_questions, out_path):
    with open(out_path, "w", newline="") as f:
        w = csv.writer(f); w.writerow(["id", "answer", "probability", "confidence"])
        for i in range(0, len(rows), BATCH):
            chunk = rows[i:i+BATCH]
            answers = ask(build_state(chunk), build_questions(chunk))
            for row in chunk:
                a = answers[row["id"]]
                w.writerow([row["id"],
                            a.get("choice") or a.get("score") or a.get("noul"),
                            a.get("noul") or max(a.get("probabilities", {}).values(), default=""),
                            a.get("confidence", "")])
# rows = list of dicts with an "id" key. build_state / build_questions come from each workflow below.
Two things in there are not optional. The backoff on 429 and 529 is what TypeSafe asks for in their API reference. And the output goes to a CSV with the probability and the confidence on every row, because the thresholds get applied afterwards in a spreadsheet or a second script, where you can see them. Never hard-code "keep if above 0.7" inside the loop on day one.
The four workflows from the post
Same four, same order. Each one is a state, a question, a threshold and one action.
Filter your full GSC export down to relevant queries
Yes/no per keyword. The one that makes the other three possible.
Why it exists: a Search Console export for a site with any age is mostly noise. Brand misspellings, queries from the one page that accidentally ranks for something irrelevant, the 2,000 long-tails with one impression. Every keyword analysis you've ever done was done on a sample because the full list was unreadable. Jev reads the full list.
State: a short description of the business (two or three sentences, what it sells and to whom) plus the batch of queries, keyed by id. Question: one noul per query, referencing that query's key. The criteria block is where you define relevance in your own terms, and it's the part you'll rewrite after the 50-row check.
{
  "model": "jev-latest",
  "state": {
    "site": "ChatSEO is an AI SEO assistant for small business owners and solo founders. It connects to Google Search Console and tells the user which page to fix next. It does not sell SEO services, courses or link building.",
    "queries": {
      "q1": "chatgpt prompts for seo",
      "q2": "how to see which pages get clicks in search console",
      "q3": "netflix cancel subscription",
      "q4": "seo agency pricing london"
    }
  },
  "questions": {
    "q1": { "type": "noul",
      "instructions": "Someone typing the query at queries.q1 into Google is a plausible customer for the business described in site.",
      "criteria": {
        "true":  "The query is about doing SEO, understanding Search Console data, or choosing an SEO tool, from the point of view of someone who owns or runs a website.",
        "false": "The query is about an unrelated topic, is looking to hire an agency or freelancer, is academic or news-driven, or is a navigational search for another product." } },
    "q2": { "type": "noul", "instructions": "Someone typing the query at queries.q2 into Google is a plausible customer for the business described in site.", "criteria": { "true": "same as above", "false": "same as above" } },
    "q3": { "type": "noul", "instructions": "Someone typing the query at queries.q3 into Google is a plausible customer for the business described in site.", "criteria": { "true": "same as above", "false": "same as above" } },
    "q4": { "type": "noul", "instructions": "Someone typing the query at queries.q4 into Google is a plausible customer for the business described in site.", "criteria": { "true": "same as above", "false": "same as above" } }
  }
}
In production your script generates the four questions, and the "same as above" is the full criteria text repeated, because Jev evaluates each question independently and doesn't read the others. It's more tokens. At $0.042 per million, you will not notice.
Thresholds: noul ≥ 0.8 keep. noul ≤ 0.2 drop. Between the two, keep it but tag it review, and read the 40 highest-impression ones in that band by hand. Expect the band to hold 10 to 20 percent of rows on the first run and to shrink every time you sharpen the criteria.
One action: the keep list, joined back to clicks, impressions and position, becomes your working keyword set. Everything else on this page runs on that set and nothing else. Do not run workflows 2 to 4 on the raw export.
Classify intent and funnel stage into your taxonomy
Wrong output is impossible by design. If your taxonomy has five intents, you get one of the five.
Why it exists: every intent classifier you've used either forced Google's four buckets on you or let an LLM invent a sixth category on row 300. A choice question is the opposite: the options are yours, they're closed, and each one gets a probability. Two questions per query in one request, because Jev runs them in parallel and it costs nothing extra in latency.
State: the same business description, plus the batch of queries with their top-ranking page URL from the export if you have it. The URL is a strong signal for navigational intent and it's free. Questions: for each query, one choice for intent and one for funnel stage. The options below are mine. Replace them with yours, but keep the descriptions concrete: the docs are explicit that options which describe a situation beat options that describe a degree.
{
  "model": "jev-latest",
  "state": {
    "site": "ChatSEO is an AI SEO assistant for small business owners and solo founders. It connects to Google Search Console and tells the user which page to fix next.",
    "queries": {
      "q7":  { "text": "best ai seo tools 2026", "ranking_url": "/blog/ai-seo-tools" },
      "q8":  { "text": "chatseo pricing", "ranking_url": "/pricing" }
    }
  },
  "questions": {
    "q7_intent": { "type": "choice",
      "instructions": "What is the searcher at queries.q7 trying to do?",
      "criteria": {
        "informational": "Learn how something works or how to do it. No sign of wanting to buy or pick a product.",
        "commercial":    "Compare, shortlist or evaluate products or approaches before choosing one.",
        "transactional": "Sign up, buy, download, get pricing or start using a specific thing now.",
        "navigational":  "Reach a specific brand, product or page they already know.",
        "other":         "None of the above, or the query is too ambiguous to place." } },
    "q7_stage": { "type": "choice",
      "instructions": "Where is the searcher at queries.q7 in the buying journey for the business described in site?",
      "criteria": {
        "top":    "Has the problem, does not yet know solutions like this exist.",
        "middle": "Knows solutions exist, is working out which kind or which one.",
        "bottom": "Has chosen or nearly chosen, wants to start, price, or confirm a detail.",
        "none":   "Not on a journey toward this business at all." } },
    "q8_intent": { "type": "choice", "instructions": "What is the searcher at queries.q8 trying to do?", "criteria": { "informational": "…", "commercial": "…", "transactional": "…", "navigational": "…", "other": "…" } },
    "q8_stage":  { "type": "choice", "instructions": "Where is the searcher at queries.q8 in the buying journey for the business described in site?", "criteria": { "top": "…", "middle": "…", "bottom": "…", "none": "…" } }
  }
}
Always include an other or none option. The docs recommend it, and the reason is practical: without an escape hatch, an ambiguous query gets forced into your best-sounding bucket with a probability that looks more certain than it is.
Thresholds: this is where confidence earns its keep. confidence ≥ 0.9: accept both labels. 0.5 to 0.9: accept, but the row carries a flag and you don't build anything on it without a glance. < 0.5: it goes in a review sheet. The probabilities are still there for every row, so a query that's 0.48 commercial and 0.47 transactional tells you something useful: it's a comparison page with a CTA.
One action: pivot the result by stage × intent, filter to bottom + transactional or commercial, sort by impressions, and find the first query in that list whose ranking URL is a blog post or is empty. That's the page you brief this week. Not the list. That one.
Detect cannibalisation across every page pair on your site
Not "which queries have two URLs". Which pairs of pages are actually competing for the same intent, and which one should win.
Why it exists: the usual cannibalisation check is a pivot on the query + page export: any query with two URLs is "cannibalised". Half of those are fine (a pricing page and a comparison page both ranking for a brand term). The real question, same intent or not, is a judgment. It was too expensive to make for every pair, so nobody did. At Jev's price you can, and the answer comes with a recommendation attached.
Before Jev sees anything, code does the pre-filter. Do not send every page pair on your site. A 400-page site has 79,800 pairs and almost all of them are obviously unrelated. From the query + page export, build the list of page pairs that share at least one query with impressions. That's usually a few hundred pairs. Those are the candidates.
State: for each pair, the two pages' URL, title, H1, meta description and their top five shared queries with impressions. Keep it to that. Full page bodies are exactly the "irrelevant state" the jaggedness page warns about. Questions: three per pair, in parallel.
{
  "model": "jev-latest",
  "state": {
    "pairs": {
      "p1": {
        "a": { "url": "/blog/what-is-search-console", "title": "What Is Google Search Console? A Beginner's Guide", "h1": "What is Google Search Console?", "meta": "Everything a beginner needs to know about GSC." },
        "b": { "url": "/blog/search-console-tutorial", "title": "Google Search Console Tutorial (2026)", "h1": "How to use Google Search Console", "meta": "Step-by-step tutorial for GSC." },
        "shared_queries": [
          { "q": "google search console tutorial", "impressions": 4200 },
          { "q": "what is search console", "impressions": 1900 },
          { "q": "how to use search console", "impressions": 1400 } ] }
    }
  },
  "questions": {
    "p1_same_intent": { "type": "noul",
      "instructions": "Pages pairs.p1.a and pairs.p1.b are written to satisfy the same searcher need, such that one page could serve every query in pairs.p1.shared_queries.",
      "criteria": {
        "true":  "Both pages explain or teach the same thing to the same kind of reader. A searcher would be equally served by either.",
        "false": "The pages serve different needs: one defines, the other instructs; one compares, the other sells; or they target different audiences or stages." } },
    "p1_winner": { "type": "choice",
      "instructions": "If only one page in pairs.p1 should exist, which one, based on how well its title, H1 and meta match pairs.p1.shared_queries?",
      "criteria": {
        "a": "Page a's title, H1 and meta match the shared queries better.",
        "b": "Page b's title, H1 and meta match the shared queries better.",
        "neither": "Both should exist; they serve different needs." } },
    "p1_severity": { "type": "score",
      "instructions": "How much does the overlap between pairs.p1.a and pairs.p1.b hurt?",
      "criteria": [
        "Cosmetic overlap. Different needs, a shared brand or generic term.",
        "Partial overlap. One or two shared queries could go to either page.",
        "Direct competition. Same need, same queries, two pages splitting the signal." ] }
  }
}
Three questions instead of one because they fail differently. same_intent is the decision. winner is the plan. severity is the priority. When same_intent is high and winner is neither with low confidence, you've found the pair a human needs to look at, and you've found it in a list of 400 instead of by accident.
Thresholds: a pair is a merge candidate when same_intent ≥ 0.9 and severity ≥ 1.5 and winner has confidence ≥ 0.7. Sort candidates by total shared impressions.
One action: the top pair on that list gets consolidated this week: the loser 301s to the winner, the winner absorbs any section the loser had that the winner didn't. One pair. Then you measure it for 28 days before touching the next one, because "we merged 15 pages in a weekend" is how people find out their cannibalisation checker was wrong.
Score AI drafts before publishing
Auto-approve the sure ones. Review the rest. Never read a draft that was going to pass anyway.
Why it exists: if you generate content at any volume, the bottleneck moved from writing to reviewing a long time ago. Using a frontier model as the reviewer is slow, costs more than the draft did, and gives a different verdict on Monday than on Tuesday. LangChain measured GPT and Claude judges at 92 to 913 times the score variance of Jev on identical inputs. A reviewer that changes its mind between runs is not a gate, it's a coin.
State: the brief (target query, intent from workflow 2, the three things the piece must cover, the claims it's allowed to make) and the draft, split into a list of paragraphs so questions can point at them. One draft per request. This is the one workflow where the state is large, so don't batch drafts together. Questions: a mix, and note the one thing none of them ask.
{
  "model": "jev-latest",
  "state": {
    "brief": {
      "target_query": "how to find pages losing clicks in search console",
      "intent": "informational",
      "must_cover": [ "the Pages report and the date comparison", "how to spot a drop that's a query loss vs a position loss", "what to do first when a page drops" ],
      "allowed_claims": [ "GSC data lags by roughly 2 days", "the Compare tab supports custom date ranges" ]
    },
    "draft": {
      "title": "How to Find Pages Losing Clicks in Search Console",
      "paragraphs": [ "…", "…", "…" ]
    }
  },
  "questions": {
    "matches_intent": { "type": "noul",
      "instructions": "The draft answers brief.target_query in the way a searcher with brief.intent intent expects, rather than selling, listing tools, or drifting to a related topic." },
    "coverage": { "type": "score",
      "instructions": "How completely does the draft cover the items in brief.must_cover?",
      "criteria": [ "Covers none of them.", "Covers one, or mentions the others without explaining.", "Covers most of them properly.", "Covers every item with enough detail to act on." ] },
    "unsupported_claim": { "type": "noul",
      "instructions": "The draft states at least one specific factual claim, number or product behaviour that is not in brief.allowed_claims and not common knowledge.",
      "criteria": { "true": "There is a concrete, checkable statement that the brief did not license.", "false": "Every specific claim is either in brief.allowed_claims or is general enough not to need a source." } },
    "sounds_generated": { "type": "score",
      "instructions": "How much does the draft read like unedited AI output?",
      "criteria": [ "Reads like a person with a point of view wrote it.", "Mostly fine, some filler or generic transitions.", "Padded, repetitive, or opens with a definition nobody asked for." ] },
    "verdict": { "type": "choice",
      "instructions": "What should happen to this draft?",
      "criteria": {
        "publish": "Ready as is, or with edits a proofreader would make.",
        "revise":  "Right piece, specific gaps: a missing must_cover item, a claim to remove, a section to cut.",
        "rewrite": "Wrong intent, wrong angle, or would need more than half its text changed." } }
  }
}
The thing none of these ask: how long is it, does it have an H2 every 300 words, does the target query appear in the first 100 words. Jev can't count and shouldn't be asked to. Those are five lines of code that run before the request, and a draft that fails them never reaches Jev at all.
Thresholds: auto-approve when verdict = publish with confidence ≥ 0.9, matches_intent ≥ 0.9 and unsupported_claim ≤ 0.1. All three. Anything else goes to the review queue with the failing question's name attached, so the reviewer opens the draft knowing what to look for instead of reading it cold.
One action: publish the auto-approved drafts. Then open the review queue sorted by coverage ascending and fix the worst one. If the auto-approve rate is above 60 percent on the first week, your thresholds are too loose, not your drafts too good. Tighten until you catch one you'd have caught yourself.
The routine, so four workflows don't become four jobs
Each workflow runs on a different clock, and three of them run without you.
| Workflow | Runs | Triggered by | You read |
|---|---|---|---|
| 1 · Filter | Monthly | A fresh 16-month export | The review band's top 40, once |
| 2 · Classify | Monthly, right after 1 | The new keep list | One row: the next page to brief |
| 3 · Cannibalisation | Monthly, after 2 | The query + page export | One pair: the merge for this month |
| 4 · Draft scoring | Every draft | A draft landing in the folder | The review queue, worst first |
The first three are one script, one morning a month, in that order, because each one's input is the previous one's output. The fourth is a hook on your content pipeline. Total reading time per month, if the thresholds are right: under an hour. Total judgments made on your behalf in that month: somewhere in the tens of thousands.
And the reason to run it monthly rather than daily is not cost. It's that the actions at the end of each workflow (brief one page, merge one pair) take Google weeks to reflect. Re-judging the same export every day produces the same list with more noise.
Where this playbook stops, and where I'd want the employee to start. Every request above judges. None of them sees. Jev doesn't pull your Search Console, doesn't know which of the 4,000 queries it just kept gained or lost position since last month, doesn't open the page it just told you to merge, and doesn't check 28 days later whether the merge worked. That loop, and the part where the one action actually ships, is still you, a script and a spreadsheet.
That's the gap ChatSEO is built to close: it's connected to your Search Console, so the judgment lands on live numbers, the action gets pushed to your CMS, and the recheck is on the calendar before you've closed the tab. The day Jev is in its toolbox, the four workflows on this page are what it runs underneath. Until then, they're what I'd run by hand.
The five mistakes I expect to make first
Written before I've made them, from the docs and from every classifier I've ever shipped.
- Trusting the probability without the 50-row check. A calibrated 0.92 is only calibrated on the distribution it was trained on. Your queries aren't that. Fifty hand-labelled rows per workflow, before any threshold is chosen, is the whole quality process.
- Asking a negated question. "Is this query irrelevant" reads naturally and fails in a way you won't notice for a month. Every noul on this page is phrased so that yes is the positive case, and the docs warn that
P(x)and1 − P(not x)are not the same number. - Stuffing state. Sending the full page HTML to the cannibalisation check, or the whole business plan as the site description. Accuracy drops with unrelated context, and the docs say so. Title, H1, meta, top queries. Stop there.
- Asking Jev to count or compare numbers. "Did this page's clicks fall by more than 20 percent" is a spreadsheet formula. The model reads numbers as text and will give you a confident answer that's wrong. Code does arithmetic. Jev does judgment.
- Acting on the whole list. Merging every flagged pair, briefing every bottom-funnel query, publishing every auto-approved draft on the same day. Each workflow ends in one action for a reason: it's the only way to learn whether the judgment was right before you've made it four hundred times.
Where it still needs you
Writing the criteria. Every question on this page has a criteria block, and that block is your SEO judgment, compressed. Jev applies it fifty thousand times; it doesn't invent it. If your definition of "relevant" is fuzzy, you get fuzzy at scale, fast and cheap. The 50-row check is really a check on your criteria, not on the model.
Deciding what to do about it. A merge list is not a merge. A bottom-funnel query with no page is not a page. The judgment got cheap. The action didn't, and the action is still the part that moves clicks.
How one founder went from 250 → 750 clicks a day
This is the Search Console graph from a ChatSEO user running a loop built on exactly these judgments: which queries matter, which page owns them, which fix to ship first, and a recheck at 28 days. No new content, no link building. The tool made the judgments; the founder shipped the one action a week.
Why this works when SEO tools don't
Everything on this page is four questions and a loop, and you can try the employed version for free if you'd rather not be the one running it.
Old SEO tools
- A sample of 500 keywords, and a guess about the rest
- Intent buckets that belong to the tool, not to you
- "Cannibalisation" means two URLs, not two pages fighting
- A reviewer that gives a different verdict every run
- A dashboard of findings and no one to act on them
What you actually want
- Every keyword judged, for a dime
- Your taxonomy, closed, with a probability per label
- Same intent or not, per pair, with the winner named
- The same answer on Monday and Tuesday
- One action, shipped, rechecked at 28 days
That's the whole idea behind ChatSEO
Thousands of tiny judgments, made on your live Search Console data, rolled up into the one thing to do next. Jev makes the judgments cheaper. ChatSEO is the employee that runs them for you.
Get your SEO employee free →No credit card required